Give Your Optimizely Devs (and Agents) Visual Guardrails to Prevent Bugs. Save your spot for the Oct. 29th webinar
Give Your Optimizely Devs (and Agents) Visual Guardrails to Prevent Bugs. Save your spot for the Oct. 29th webinar
AI is taking over more of the execution in software delivery. In Who’s Watching the Agents? Context, Guardrails, and Front-Line Reality, Beth Marshall, Paul Grizzaffi, and Ivan Davidov set the marketing aside and talked about what agentic testing looks like in practice.
Their shared conclusion: keeping quality accountable when humans step back is the hardest thing now.
Ivan has lived the whole arc, starting with chatbots, then prompt engineering, context engineering, and now harness engineering. The principle behind the progression is simple. As agents have improved, we build the workflow the way a human works: understand the ticket, find the constraints, explore test cases, and verify each step before moving onto the next.
“The main idea and the main design of the agents is to complete the task. We are here to define what is the task and what done actually means.” – Ivan Davidov
How hands-off you go depends on risk. Paul’s rule: the fewer human eyes on the output, the more risk you’re taking on. A team with loose cost of change and risk-tolerant clients can pull back. Medical, aviation, and financial systems can’t. Some things an agent can’t judge at all, like whether an experience is actually fun.
Agents optimize for the green check mark, and they’ll take the shortest path to get it. The panel shared three examples:
None of these were catastrophes, all would have shipped as passing work.
“If you are blindly relying on these things and you are not being critical of the output, we risk a lot of false positives, and that being much more of an issue than it ever used to be.” – Beth Marshall
According to Paul, we fix this by defining not just done and ready, but good. What fit-for-purpose looks like, spelled out, because agents won’t add skepticism of their own.
Ivan’s sharpest warning was technical. Agents are very good at producing evidence: reports, green runs, summaries that read like proof. That is different from evidence of tests that actually executed and asserted something.
He has seen tests with 12 steps and not a single assertion. They pass every time and verify nothing. Generated evidence builds confidence in no one, so the job is to validate every output and confirm that what ran was the right test.
For a business the ideal pipeline has always been as few people as possible seeing a ticket from creation through to completion. As agents move us closer to this, we increase the risk of missing oversight.
“We need more of the breadcrumbs. Here’s what happened, here’s what did not happen, and here’s what we wanted to see if it happened or not… Things are becoming more opaque because they’re becoming more programmatic.” – Paul Grizzaffi
When execution becomes opaque, green checkmarks aren’t proof of quality. The challenge isn’t just generating runs faster—it’s capturing those breadcrumbs before human oversight disappears completely.
The panel pointed leaders at three areas:
Testing is moving toward developers, and not always carefully. Paul expects crank turning, running scripts and checking outputs, to go away. In its place, intent will grow. Building guardrails, reading risk, and tuning agents to do the execution.
Agents will keep getting faster. The real advantage is knowing when to trust what they tell you.
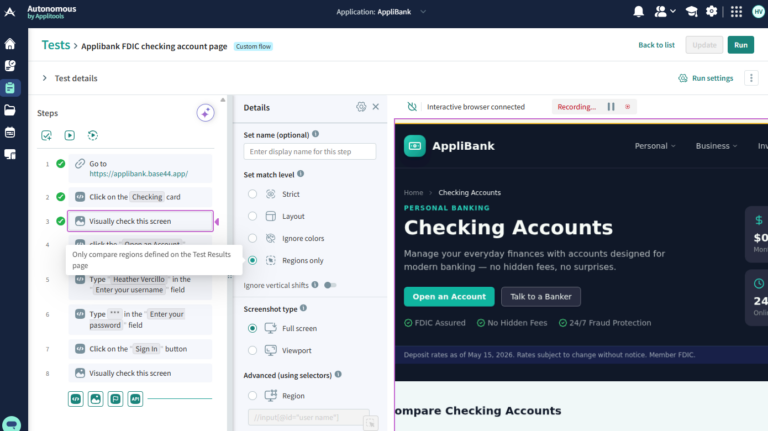
That independent verification is where platforms like Applitools fit into the harness: acting as visual and functional guardrails that provide the immutable breadcrumbs human reviewers need to confirm that a passing agent run actually delivered a working user experience.
Guardrails are the constraints, context, and verification loops built around an AI agent so its output stays in scope and fit for purpose. This includes clear definitions of done and good, limits on what the agent can change, and human review where risk is high.
It depends on risk and risk-tolerance. Teams with a low cost of change and risk-tolerant customers can use fewer checkpoints; life-critical and financial systems need more.
Generated evidence is output an agent produces that looks like proof of testing. Executed evidence comes from tests that actually ran and asserted something. A test with many steps and no assertions produces only generated evidence.
Repetitive execution is being automated, and the role is shifting toward managing and architecting agentic systems. Defining intent, building guardrails, assessing risk, and doing human-centered testing agents can’t.